Starport
Starport is a self-hosted LLM inference gateway in one binary.
Install
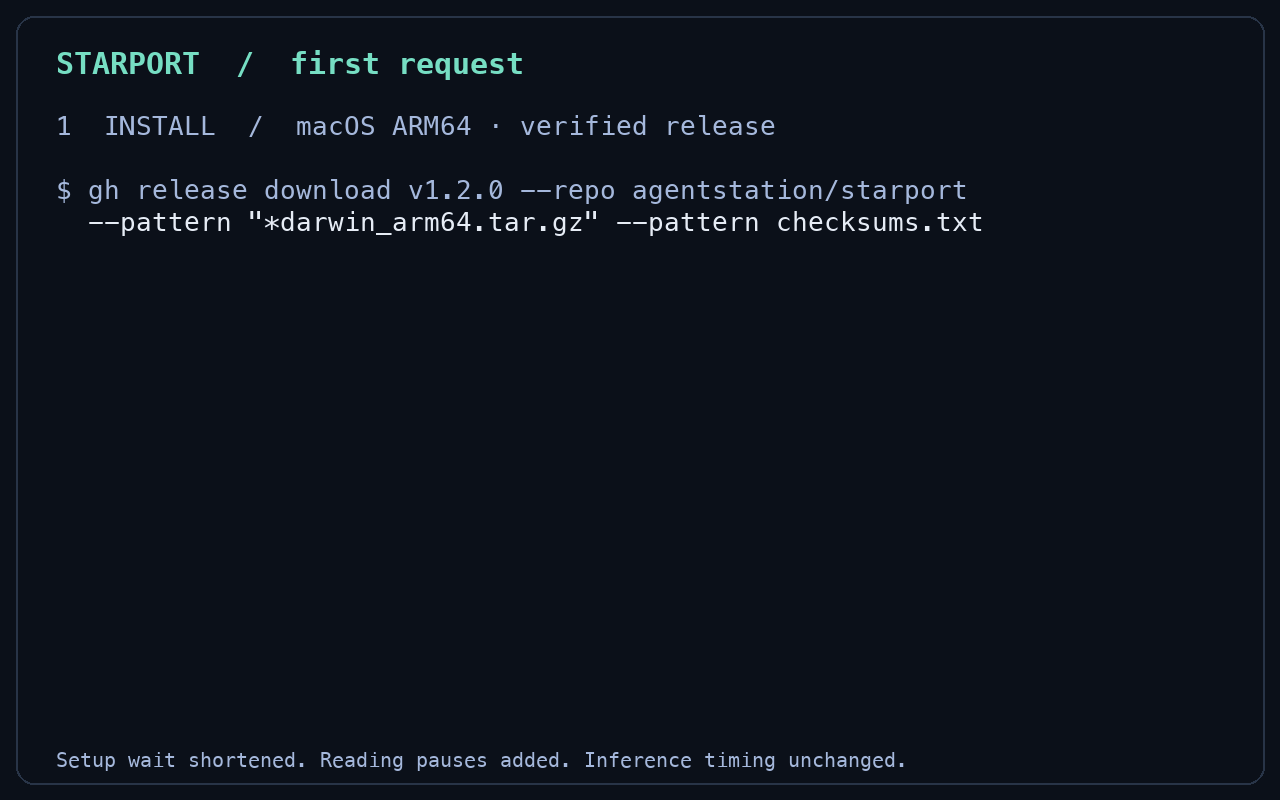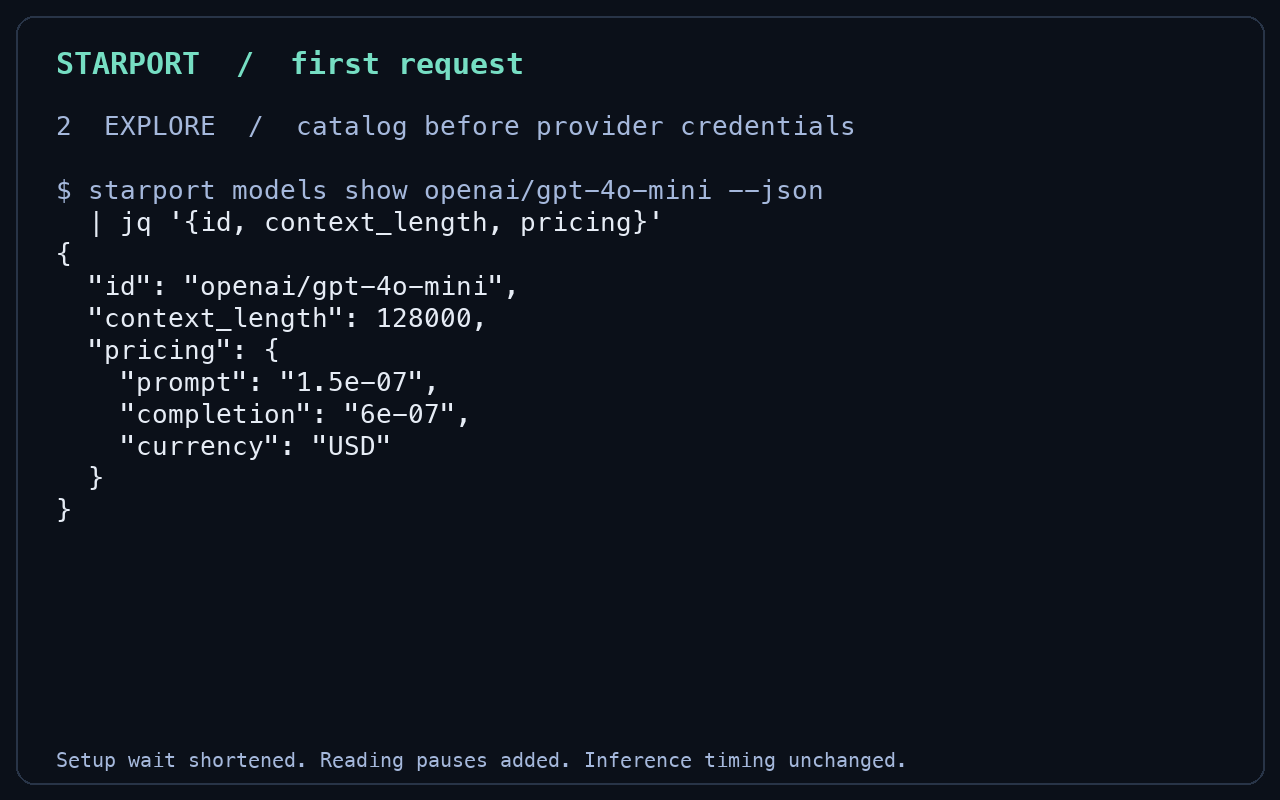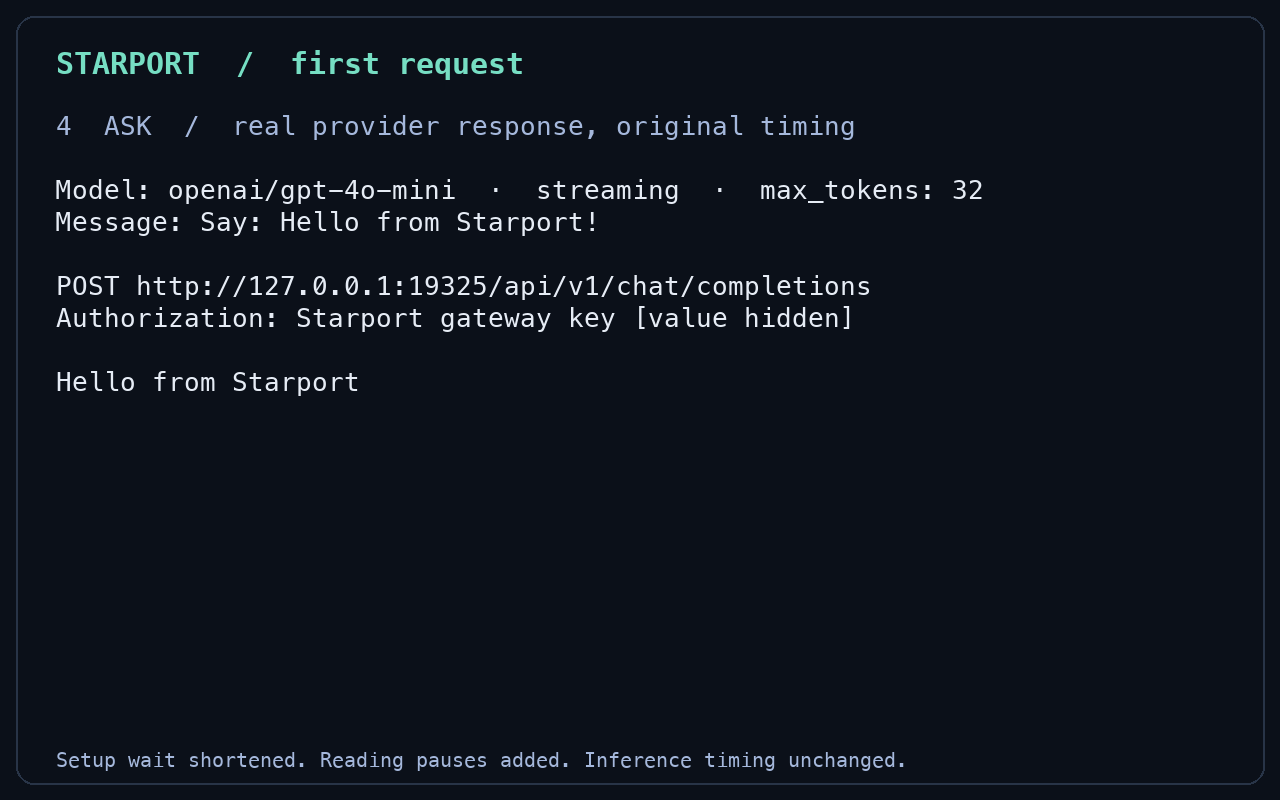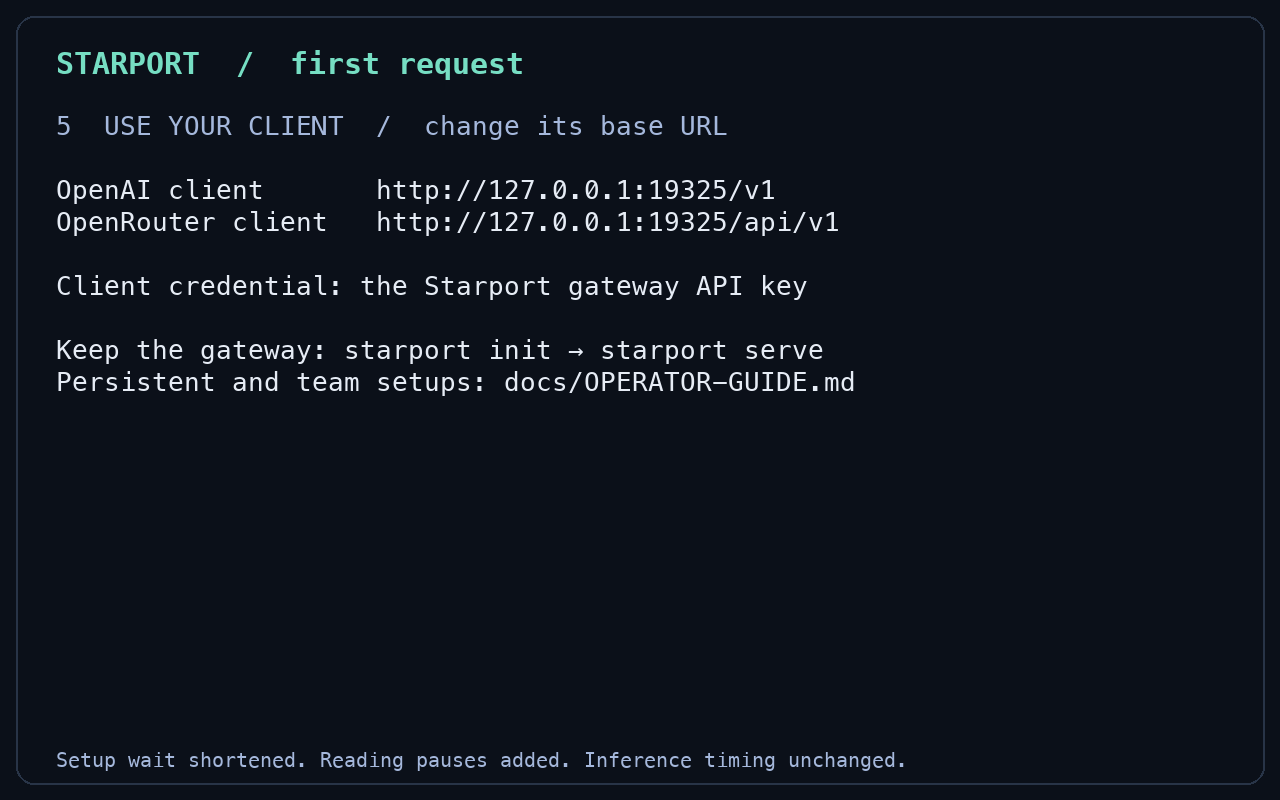
Supported targets are macOS on Apple silicon, Linux on x86-64 and ARM64, and Windows on x86-64 and ARM64. Checksummed archives for macOS, Linux, and Windows are on GitHub Releases.
Homebrew
Install the released cask on macOS or Linux.
brew trust --cask agentstation/tap/starport
brew install --cask agentstation/tap/starport
starport --version
Container image
Pull a versioned image and verify its GitHub attestation.
STARPORT_VERSION="$(gh release view \
  --repo agentstation/starport \
  --json tagName \
  --jq '.tagName | ltrimstr("v")')"
docker pull "ghcr.io/agentstation/starport:$STARPORT_VERSION"
gh attestation verify "oci://ghcr.io/agentstation/starport:$STARPORT_VERSION" \
  --repo agentstation/starport \
  --signer-workflow agentstation/starport/.github/workflows/release.yaml
docker run --rm "ghcr.io/agentstation/starport:$STARPORT_VERSION" --version
Quick start
Start a temporary gateway with one provider inference credential. It keeps no state after it stops.
unset STARPORT_CATALOG_STATE_DIR STARPORT_FILES_BACKEND
export OPENAI_API_KEY="replace-with-provider-inference-key"
starport dev